
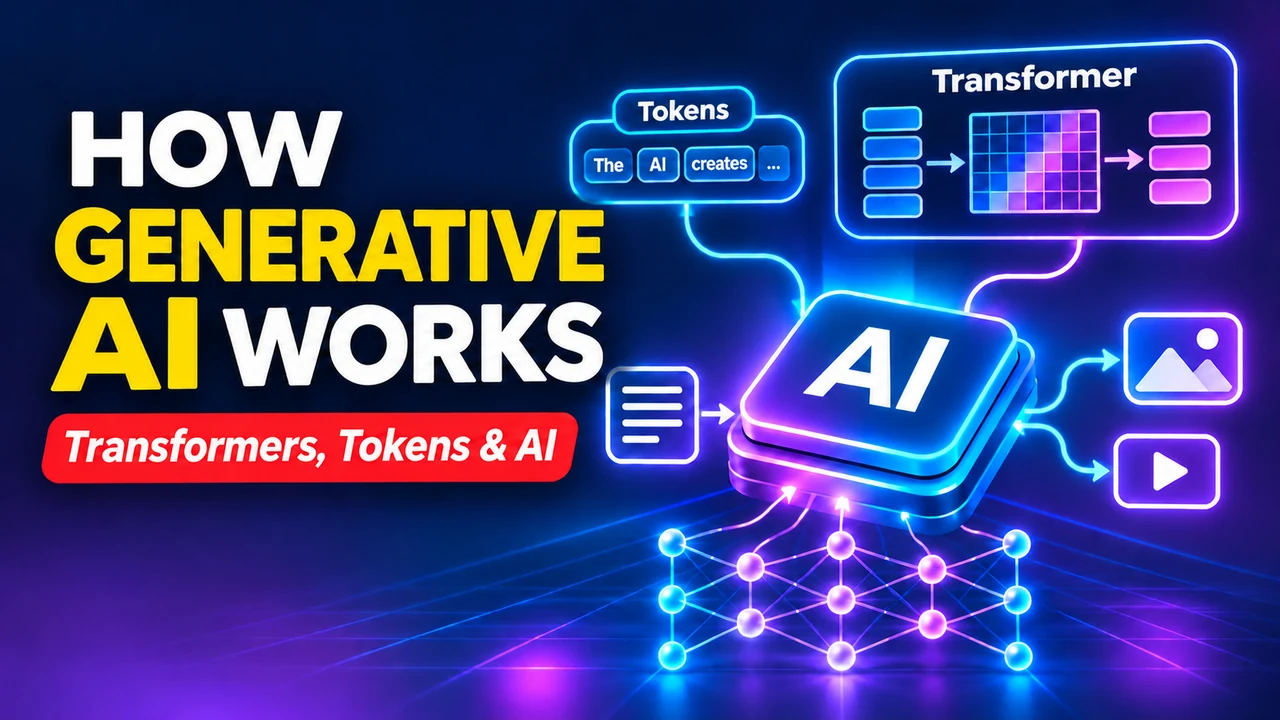
Updated October 31, 2026. How does a generative AI system transform text into predictions? At its core are numerical representations, neural-network layers, optimization and attention. This developer-oriented guide explains those mechanisms with small calculations and runnable Python. It focuses on autoregressive language models; image generation may use different techniques such as diffusion.
Learning path: Start with neurons and gradients, then move through tokenization, embeddings, Transformer attention, model training and next-token decoding. The numbers in this guide are educational examples, not measurements of commercial models.
1. Neural networks: A weighted calculation
A simple artificial neuron combines inputs with learned weights and a bias: z = w1*x1 + w2*x2 + b. A non-linear activation may then transform this value. For x1=2, x2=3, w1=0.5, w2=0.2, b=0.1, the result is z = 0.5*2 + 0.2*3 + 0.1 = 1.7. With the ReLU activation max(0,z), the output remains 1.7. If z were negative, ReLU would return zero.
Real neural networks operate on vectors and matrices and contain many connected layers. Their parameters are learned from data; the neuron analogy is useful but does not mean a model thinks like a biological brain.
2. How training changes model weights
Training uses a loss function to measure the model’s prediction error. Backpropagation computes gradients showing how changing parameters would change that loss. An optimizer takes a step, often using the rule new_weight = old_weight - learning_rate * gradient.
Consider a toy model whose parameter starts at w=2, with gradient dL/dw=0.4 and learning rate 0.1. One gradient-descent update gives w_new = 2 - 0.1*0.4 = 1.96. The gradient is a derivative: it describes the local rate of change of loss with respect to the weight. This single step does not guarantee globally optimal performance.
Many modern models use more sophisticated optimizers, batches, normalization and learning-rate schedules. Training changes parameters; inference normally uses fixed trained parameters to generate an answer.
3. What is a Transformer?
The Transformer architecture was introduced by Vaswani and colleagues in “Attention Is All You Need” (2017). It combines attention with feed-forward transformations, positional information, normalization and residual connections. Its design enabled more parallel computation during training than traditional recurrence-based sequence models.
Different Transformers have different arrangements. Some are encoder-only, some decoder-only, and others encoder-decoder. Many generative text models use an autoregressive decoder style with causal attention. They can process a prompt using parallel hardware operations, but the final answer is generally generated one token at a time.
4. Tokenization: Converting text into units
Before a language model processes text, a tokenizer converts it into token IDs. Tokens may represent words, fragments, punctuation or other byte-based units depending on the vocabulary. The exact token IDs for a phrase are tokenizer-specific; do not assume that “ChatGPT” is always split the same way.
For a made-up tokenizer, the string “reading books” might become the units ["read", "ing", " books"]. A different tokenizer could produce another split. The actual model sees integer IDs, not literal English words as separate conceptual objects.
5. Embeddings and positional information
A learned embedding table maps each token ID to a vector, a list of numbers. For example, one token might have a toy vector [0.2, -0.1, 0.7]. This is not a sentiment score or a human-readable definition; it is a learned representation used by the network.
Order also matters. “Dog bites person” differs from “Person bites dog.” Transformer variants encode token position using different techniques, such as added positional embeddings or rotary positional representations. The idea is the same: provide information about sequence position alongside content.
6. Self-attention: Queries, keys and values
In self-attention, each token representation is transformed into three vectors: a query (Q), key (K) and value (V). A query is compared with keys to determine attention scores. Softmax converts scores to nonnegative weights that sum to one. The output is the weighted sum of the values.
The scaled dot-product formula is:
Attention(Q,K,V) = softmax((Q K^T) / sqrt(d_k)) V
K^T means the transpose of K, and d_k is the dimensionality of key vectors. Scale division prevents large dot products from driving excessively sharp softmax distributions in common settings.
A two-token attention calculation
For a single query, suppose the already-scaled attention scores are [0, ln(3)]. Exponentiating yields [1,3]; divide by the sum 4 to obtain softmax weights [0.25,0.75]. If the value vectors are V1=[2,0] and V2=[0,4], the attention output is:
0.25 * [2,0] + 0.75 * [0,4] = [0.5, 3.0]
This toy calculation shows how attention combines information; it does not establish that a model has understood the sentence correctly.
7. Causal masking and multi-head attention
In autoregressive language generation, a causal mask prevents a token position from attending to future positions in the output sequence. During training, this permits parallel computation of next-token learning signals while respecting the information available at each position. During generation, new output tokens still arrive sequentially.
Multi-head attention uses several learned Q/K/V projections, allowing multiple attention patterns to be combined. Heads are not guaranteed to correspond neatly to interpretable linguistic rules. A Transformer block also contains feed-forward layers, residual pathways and normalization. Attention alone is not the entire network.
8. From hidden states to next-token probabilities
After the network processes its context, it produces a score, or logit, for each possible next token. Softmax converts logits into probabilities:
P(i) = exp(logit_i) / sum_j exp(logit_j)
For logits [0, ln(2), ln(3)], the exponentials are [1,2,3], so the probabilities are [1/6,2/6,3/6], approximately 16.7%, 33.3%, 50%. Greedy decoding chooses the third candidate; sampling could choose any candidate with nonzero probability. Temperature changes the relative sharpness of the distribution, though output diversity also depends on other decoding settings.
The selected token becomes part of the context, and generation repeats until a stopping condition or limit is reached. Fluent output can still contain hallucinated facts, unsafe code or incorrect reasoning.
9. A runnable Python example: Softmax and attention
Save this file as attention_demo.py. It uses only Python’s standard library and implements the exact two-token example above; no API key, machine-learning library or network access is required.
import math

def softmax(scores):
    shift = max(scores)
    exps = [math.exp(s - shift) for s in scores]
    total = sum(exps)
    return [x / total for x in exps]

def weighted_sum(weights, values):
    return [
        sum(w * row[i] for w, row in zip(weights, values))
        for i in range(len(values[0]))
    ]

scores = [0.0, math.log(3)]
values = [[2.0, 0.0], [0.0, 4.0]]
weights = softmax(scores)
output = weighted_sum(weights, values)

assert all(abs(a - b) < 1e-9 for a, b in
           zip(weights, [0.25, 0.75]))
assert all(abs(a - b) < 1e-9 for a, b in
           zip(output, [0.5, 3.0]))
print("weights:", weights)
print("attention output:", output)
Run python attention_demo.py. Expected output: weights: [0.25, 0.75] and attention output: [0.5, 3.0] (minor floating-point representation differences are normal). This shows only the softmax weighting and value combination. A full attention implementation must also construct Q, K and V, calculate scaled dot products and handle masks and batches.
10. Context windows, computational costs and scaling
A model’s context window limits the amount of text and other represented information it can consider at once. The full attention-score matrix for a sequence of length n contains n*n entries, giving the standard dense-attention computation a quadratic dependence on sequence length for that component. Modern implementations can reduce memory use or use different attention patterns; do not assume every production model follows identical complexity in every circumstance.
More parameters, training compute or context do not automatically guarantee better answers. Data quality, objectives, architecture, inference cost, evaluation methods and safety controls also matter. Avoid quoting unverified model sizes: OpenAI’s GPT-4 Technical Report explicitly did not disclose GPT-4’s exact architecture or parameter count.
11. Model evaluation and common developer mistakes
- Do not treat a single convincing response as proof of correctness. Use benchmark tasks and real examples.
- Separate training, inference and retrieval. Reading documents during a conversation does not retrain model weights.
- Test decoding settings. The same prompt can produce different outputs when sampling is enabled.
- Check data leakage. Benchmark contamination can overstate performance.
- Measure operational constraints. Latency, token cost, memory usage and failure rates are part of an engineering evaluation.
- Use trustworthy references. Avoid invented architectural details for proprietary models.
Frequently asked questions
Does a Transformer read every word simultaneously?
Some operations across input positions can be parallelized, particularly during training. Autoregressive output generation still produces the sequence incrementally.
Is attention the same as understanding?
No. Attention is a learned numerical mechanism for combining information. It does not guarantee a model has reached a correct interpretation or conclusion.
Do all generative AI systems use Transformers?
No. Transformers are important in language and some multimodal models, but diffusion models, GANs and other methods are also used in generation.
Does a model learn from each chat?
Not in the sense of immediately updating model weights. Application memory, conversation context and training are separate mechanisms.
Should I start by training a giant language model?
Usually not. First learn the core mathematics and implement a small example. For applications, consider existing models and measured requirements before attempting expensive model training.
Further reading on TechDrivenz
Begin with What Is Generative AI? for a broad introduction. Then read Advanced Generative AI for Developers for deeper training topics, Building Smarter AI Apps for application design, and How to Build AI Agents for tool-oriented systems.
Conclusion
Generative language models transform tokens into vectors, process context through neural-network layers and attention, and generate output from next-token probabilities. Understanding weights, gradients, causal masking and decoding helps developers evaluate what models actually do without relying on promotional claims. Small, reproducible examples are the best place to begin.

2 thoughts on “How Generative AI Works: Neural Networks, Transformers and LLMs Explained”